

How Bayesian experimentation works
A Bayesian test combines what it sees in your data with what you knew before the test began. It asks one question: “Given the data so far, what’s the chance that variant B beats variant A?”. A frequentist test asks something else: “How odd is this data if the variants are in fact the same?”- A Bayesian test starts with a prior, a probability distribution that represents assumptions about a metric before the test begins
- Algolia combines the prior with the test’s data to calculate the posterior, an updated probability distribution that reflects the observed results.
How to interpret Bayesian results
Bayesian probabilities and “credible intervals” describe uncertainty under the test’s model and “prior”. Your test results include:- Probability to be better. For example, “Variant B has a 95% probability of beating the control.” Algolia recommends a probability of at least 95% when evaluating whether a variant outperforms the control.
- Credible interval. A range that holds the true value of a metric, with a stated chance. For example, “There’s a 95% chance that the true uplift falls between 1.2% and 4.8%.” That metric is often the gap in conversion rate between the variants. You can’t read a frequentist confidence interval this way.
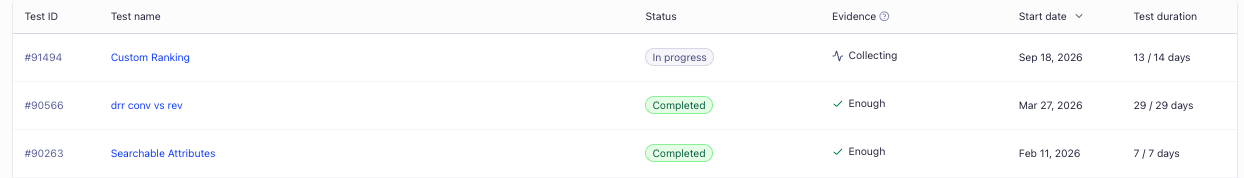
- Evidence status. Algolia computes the evidence status for the primary metric you selected when creating the test. An evidence status of “enough” means the test has gathered enough data. For Bayesian tests, this status rests on e-values. The bar is an e-value of 20 or more.
Benefits of Bayesian experimentation
- Direct answers. A probability that “variant B beats the control” answers the business question as asked.
- Frequent checks, no added risk. Fixed-duration frequentist tests can suffer the “peeking problem”: stopping when interim results become significant can increase the risk of a false positive. Algolia’s Bayesian tests account for repeated checks, so you can check as often as you like.
- No set duration up front. For frequentist tests in Algolia, you need ti plan the test duration before launch. A Bayesian test lets you follow it and stop once the evidence is strong.
How Bayesian and frequentist testing compare
Both methods are sound ways to test an idea, but they answer different questions. Neither is the better one. Frequentist testing has a long track record and firm guarantees, but its rules are strict. Algolia’s Bayesian testing gives you more flexibility in when to stop and reports results as probabilities. That flexibility fits online A/B testing, where data keeps coming in and you keep iterating.
For information about how Algolia computes frequentist confidence,
see How A/B test scores are calculated.